For over two decades, the unspoken contract of the commercial web was simple: creators and businesses provided free information, and search engines rewarded them with qualified traffic. That mutualistic ecosystem turned Google into an advertising juggernaut and transformed search engine optimization into a multibillion-dollar industry. The currency of the entire digital economy was the inbound click.
That contract is now defunct.
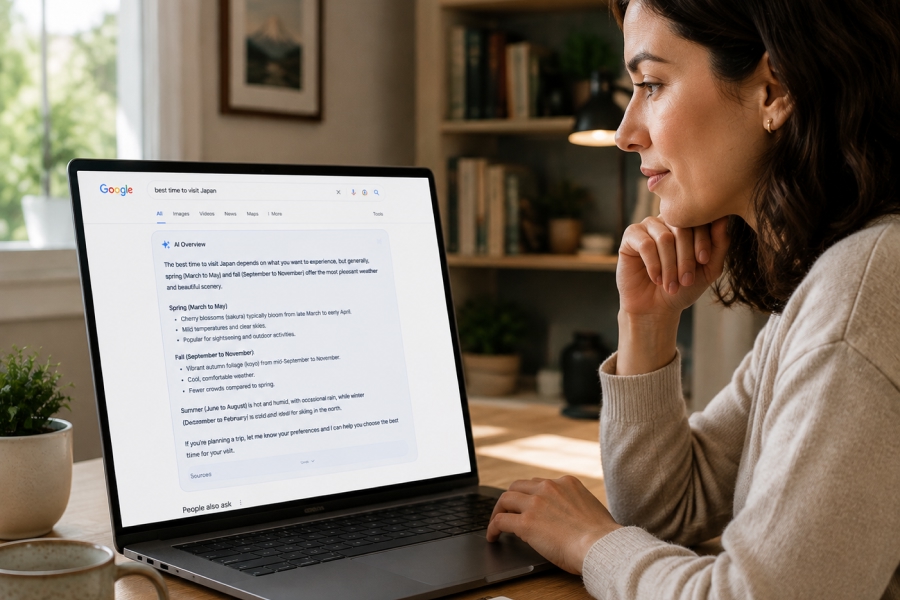
The steady rise of zero-click searches—queries resolved directly on the results page without a single outbound referral—has reached an inflection point. What began as basic weather widgets, currency converters, and featured snippets has evolved into generative AI summaries that consume the entire above-the-fold canvas. Search engines no longer serve as digital switchboards pointing visitors toward relevant destinations; they have become destination engines in their own right, synthesizing external knowledge into proprietary interfaces.
For tech companies across consumer tech, enterprise software, and specialized digital services, this transformation represents an existential threat to customer acquisition, data ownership, and brand equity. The realization is dawning across executive suites: relying on third-party discovery channels or building fragile applications on rented artificial intelligence is a road to marginalization. To survive in a world where the click is vanishing, tech firms are increasingly forced to build, fine-tune, and deploy their own proprietary large language models.
The Evaporation of the Open Web Funnel
The traditional marketing funnel was built on a predictable sequence: a user had an information gap, entered a query, scrolled through blue links, and landed on an owned website where the business could capture an email, drop a tracking pixel, or initiate a sales conversation.
Generative search destroys this sequence at the very top. When a search engine reads a dozen industry white papers, extracts their insights, and presents a polished, coherent synthesis directly to the user, the underlying publishers absorb all the hosting and research costs while capturing none of the downstream value. The user walks away satisfied, while the business that produced the underlying expertise remains invisible.
This dynamic hits enterprise tech and software providers especially hard. These companies built their go-to-market motions on high-intent educational content, technical documentation, and authoritative thought leadership. When an AI overview answers nuanced questions about API integrations, cybersecurity compliance, or cloud migration without linking to the primary documentation, prospective buyers never enter the vendor’s ecosystem.
Because organic search visibility no longer guarantees audience touchpoints, tech companies can no longer rely on external search engines as their primary bridge to potential buyers. To engage users who expect immediate, conversational answers, companies must create environments where those answers are generated inside their own products.
The Dangerous Illusion of the API Wrapper
When modern generative AI first broke into the mainstream, the instinctive reaction for many software companies was to build thin wrappers around frontier models. Licensing foundational capabilities through an external API seemed like the smartest, fastest route to market. It required minimal capital expenditure, avoided the staggering cost of training clusters, and allowed product teams to ship conversational features in weeks rather than quarters.
That playbook has quickly run into structural limitations.
Building critical customer touchpoints on someone else’s model creates immense platform dependency. Companies that rely on third-party model providers face volatile pricing structures, unpredictable model updates that silently alter application behavior, and recurring rate limits during peak demand. More fundamentally, an API wrapper concedes the most valuable asset in the modern tech landscape: direct control over the reasoning layer.
When a tech company routes all user queries through a generalized third-party model, it is essentially paying a competitor to train on its interaction patterns. The generalized model learns how enterprise users phrase questions, where users encounter friction, and which answers generate engagement. Over time, the platform hosting the API accumulates the operational intelligence, while the wrapper company remains an easily replaceable middleman.
Proprietary models break this cycle of dependency. By training or extensively adapting models on their own infrastructure, tech firms regain full governance over latency, uptime, cost structures, and feature roadmaps.
Monetizing Intent Without the Intermediary
Traditional search monetization depended on impressions and clicks, but zero-click environments require an entirely different economic architecture. Intent must now be captured, understood, and monetized within the conversation itself.
Consider how buying journeys are changing. A user no longer searches for three different project management tools, reads external review blogs, and registers for separate free trials. Instead, they prompt an AI interface with their specific team size, workflow requirements, and tech stack constraints, expecting a definitive solution.
If that interaction happens on a general-purpose public engine, the engine decides which vendor receives the recommendation based on its own training corpus and commercial incentives. For technology companies, allowing an external model to sit between their products and prospective customers means losing control over positioning, pricing transparency, and value articulation.
By developing proprietary LLMs, companies can embed domain-specific reasoning directly into their owned platforms, turning informational queries into immediate programmatic action.
From Static Answers to Agentic Fulfillment
A generic search engine can answer what a specific software workflow entails, but a proprietary model deeply integrated into a product can actually execute that workflow. This distinction separates passive zero-click engines from active agentic platforms:
-
Contextual Comprehension: Proprietary models understand the user’s historical account data, role-based permissions, and specific operational constraints in ways a general search engine never can.
-
Direct Action Execution: Rather than merely providing instructions, an owned model can execute complex multi-step database adjustments, configure system settings, or initiate procurement workflows on the spot.
-
Continuous Engagement: By keeping the entire discovery-to-resolution cycle within a dedicated interface, the company preserves customer telemetry and builds deep product stickiness.
In this environment, value shifts from owning the index of information to owning the autonomous engine that acts upon that information.
The Realities of Unit Economics and Inference at Scale
Beyond customer acquisition, the transition toward proprietary models is driven by cold computational math.
Query volumes across consumer-facing platforms and enterprise software suites are massive. Pinging a closed-source frontier model via API for every single interaction, search query, auto-complete suggestion, and background summarization quickly creates an unsustainable cost burden. The per-token pricing that appears trivial in a proof-of-concept phase turns ruinous when deployed across hundreds of thousands of daily active users.
Moreover, general-purpose frontier models are often wildly over-engineered for specific commercial use cases. A model tasked with parsing proprietary log files or answering support queries about accounting software does not need to know how to compose sonnets in iambic pentameter or explain quantum electrodynamics. Running an enormous parameter model to handle narrowly bounded tasks represents immense computational waste.
Proprietary model strategies allow engineering teams to build smaller, highly specialized architectures tailored to discrete operational domains. Through techniques like knowledge distillation, targeted pre-training, and rigorous task-specific fine-tuning, companies can deploy 7-billion to 14-billion parameter models that match or exceed the accuracy of giant frontier models on internal benchmarks.
These smaller, proprietary systems run at a fraction of the hardware cost, deliver substantially lower latency, and can run on owned cloud instances or on-premises servers. Over a multi-year horizon, the capital invested in developing tailored architectures yields vastly superior gross margins compared to paying perpetual API rents to frontier model labs.
Proprietary Data as the Sole Remaining Moat
For years, digital moats were defined by network effects, proprietary user interfaces, or massive public content libraries. Today, the public web has been aggressively scraped and assimilated into general models, while simultaneously being flooded with programmatic AI-generated content. Publicly visible text is becoming an increasingly low-value commodity.
The only genuinely defensible data left is private data: transactional histories, proprietary source code, internal operational manuals, enterprise communications, and domain-specific customer support archives.
Tech firms sit on goldmines of this protected context, but feeding that information into third-party commercial systems carries severe intellectual property and compliance liabilities. Major enterprise clients will not tolerate sensitive records passing through public APIs where data retention policies can change with an updated terms-of-service agreement.
Building an in-house proprietary model allows an enterprise to convert its internal data stores into functional intelligence without exposing proprietary assets to external systems. The resulting model serves as an institutional brain that captures organizational knowledge, encodes industry nuances, and presents users with accurate, hallucination-resistant answers that no general-purpose search engine can replicate.
Competing for the New Interface of the Digital Economy
The browser was the computing interface of the early internet; the mobile app was the interface of the past fifteen years. Today, the natural-language interface is rapidly becoming the primary layer through which humans interact with digital systems.
When users realize they can bypass traditional navigation entirely to receive immediate, synthesis-driven outcomes, they stop returning to platforms that force them to comb through links and menus. The rise of zero-click search is not merely an algorithm update—it is a fundamental migration of user habits toward conversational synthesis.
Tech companies that fail to recognize this shift risk being reduced to passive data feeds for someone else’s intelligence layer. By building proprietary models, organizations protect their brand autonomy, control their operational unit economics, and secure a direct relationship with their audience. Developing an owned model is no longer an experimental innovation initiative; it is the fundamental price of admission for remaining relevant in an era where the click is gone for good.